Archived pilot · Published runs in this database; repository bundles and earlier staging counts are separate inventories.
Archived pilot · runs from 17 Jul 2026 to 1 Oct 2026
Prüfstand
An early pilot, now an archive. We gave models a brief and show what they built from it — as a screenshot, with simple checks of the file. Not a functional test, not a ranking. Current top-tier models are not in this pilot yet.
- public runs
- 28
- models · 6 tasks
- 6
- with a check of the result
- 6/28
- judges published
- 0/28
What was tested
No model of the current frontier (OpenAI, Anthropic, Google, SpaceXAI) is represented in these runs.
Current frontier: the top-tier models of these providers as recorded by agi.jetzt; sources read 4 Oct 2026.
28 published runs of 6 models on 6 tasks. Run dates in UTC.
| Model | Runs | Tasks | Run date | Current frontier |
|---|---|---|---|---|
| Claude Haiku 4.5 | 4 | 4 | 17 Jul 2026 | no |
| GPT-5.6 Sol | 4 | 4 | 17 Jul 2026 | no |
| Claude Fable 5 | 6 | 6 | 18 Jul 2026 | no |
| GPT-5.6 Luna | 6 | 6 | 18 Jul 2026 | no |
| Phi-4-mini-instruct | 3 | 2 | 30 Aug 2026, 1 Oct 2026 | no |
| Qwen3.8-27B | 5 | 5 | 3 Sept 2026 | no |
Filled dot: a run with at least one check of the result. Empty dot: a run without one.
Datenviz-Dashboard mit Insights
frontend-dashboard-002-aA · Claude Fable 5 · model + harnessB · Claude Haiku 4.5 · model + harness
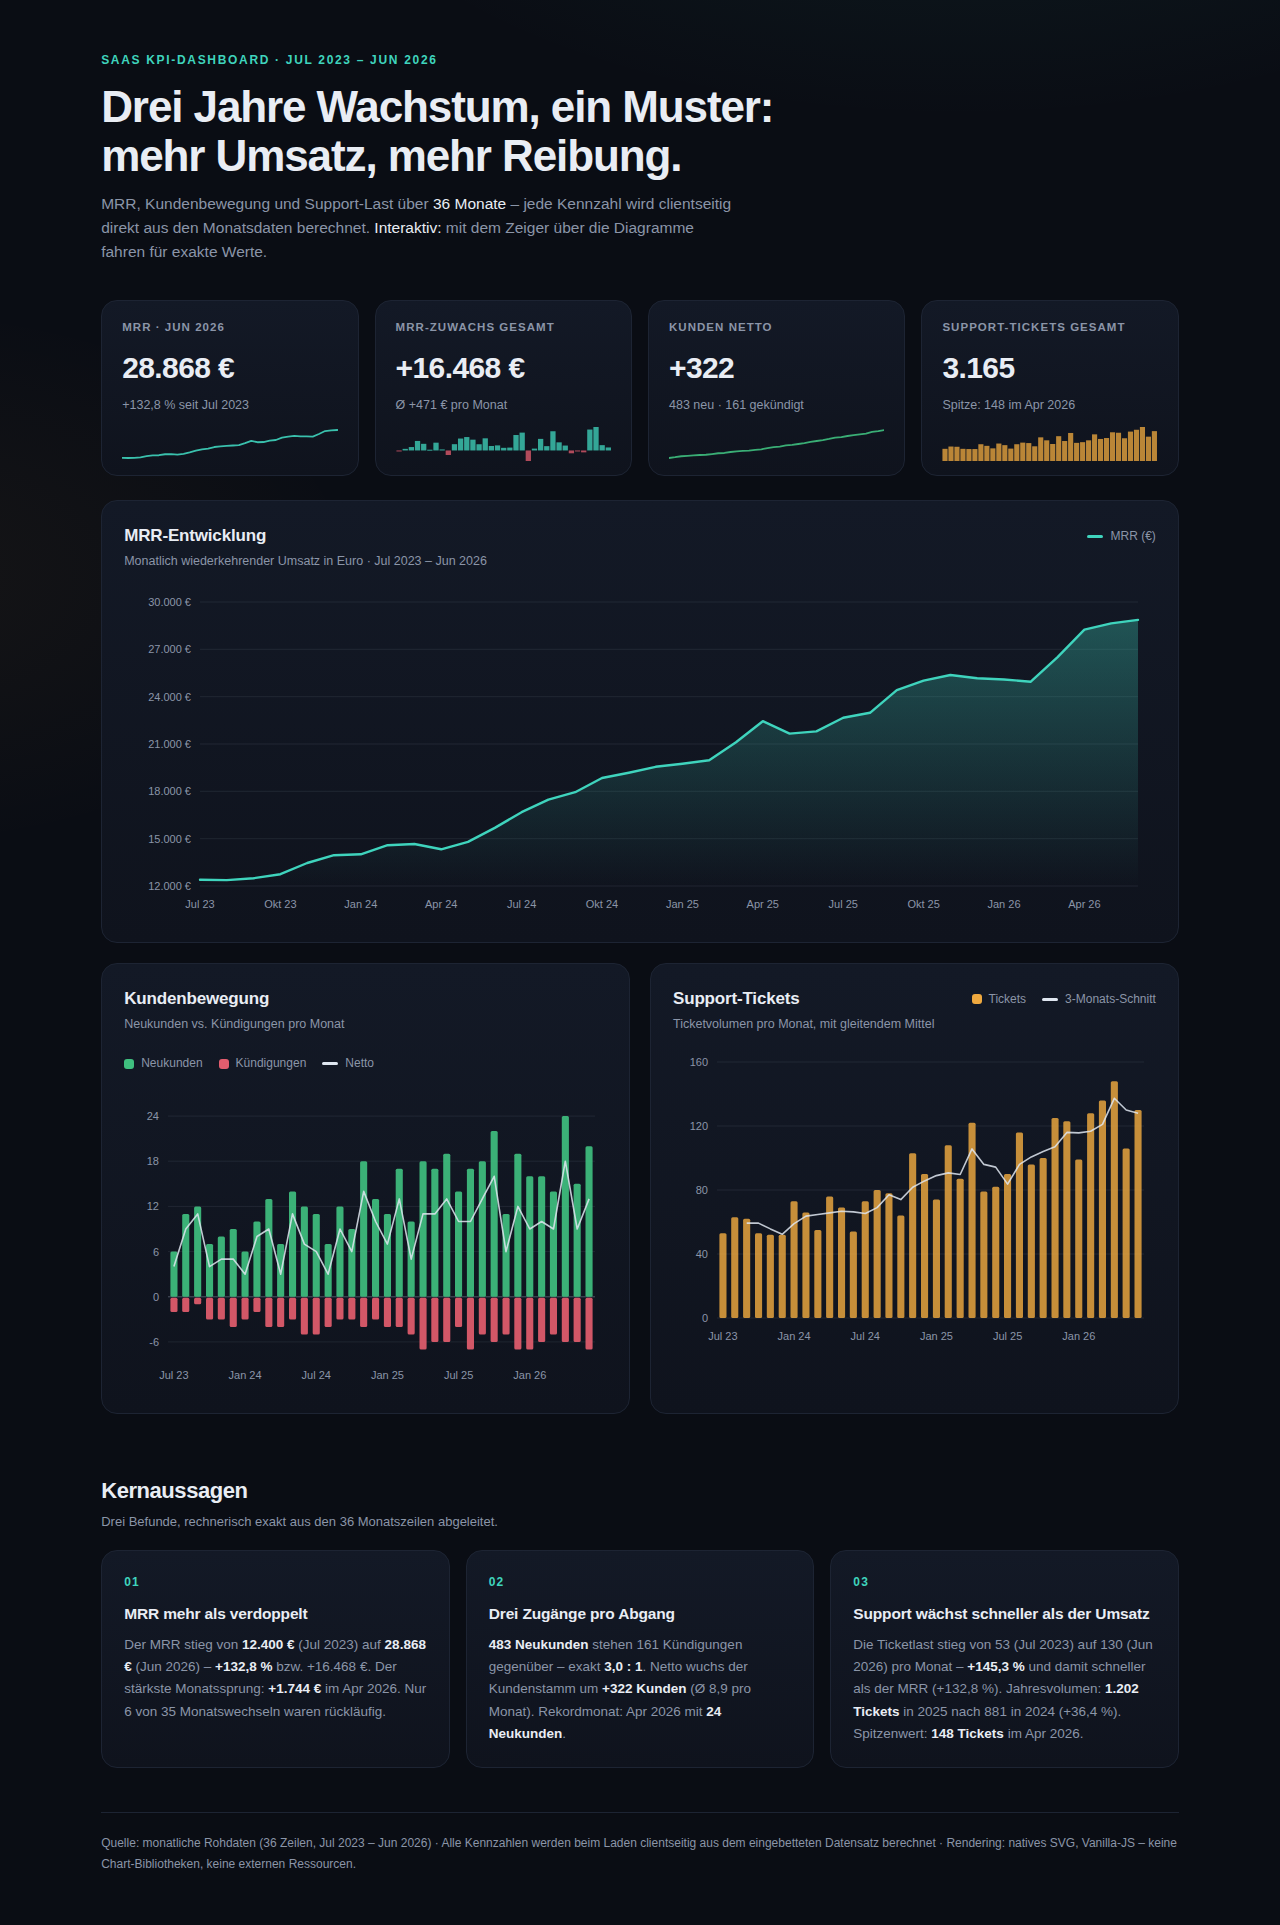
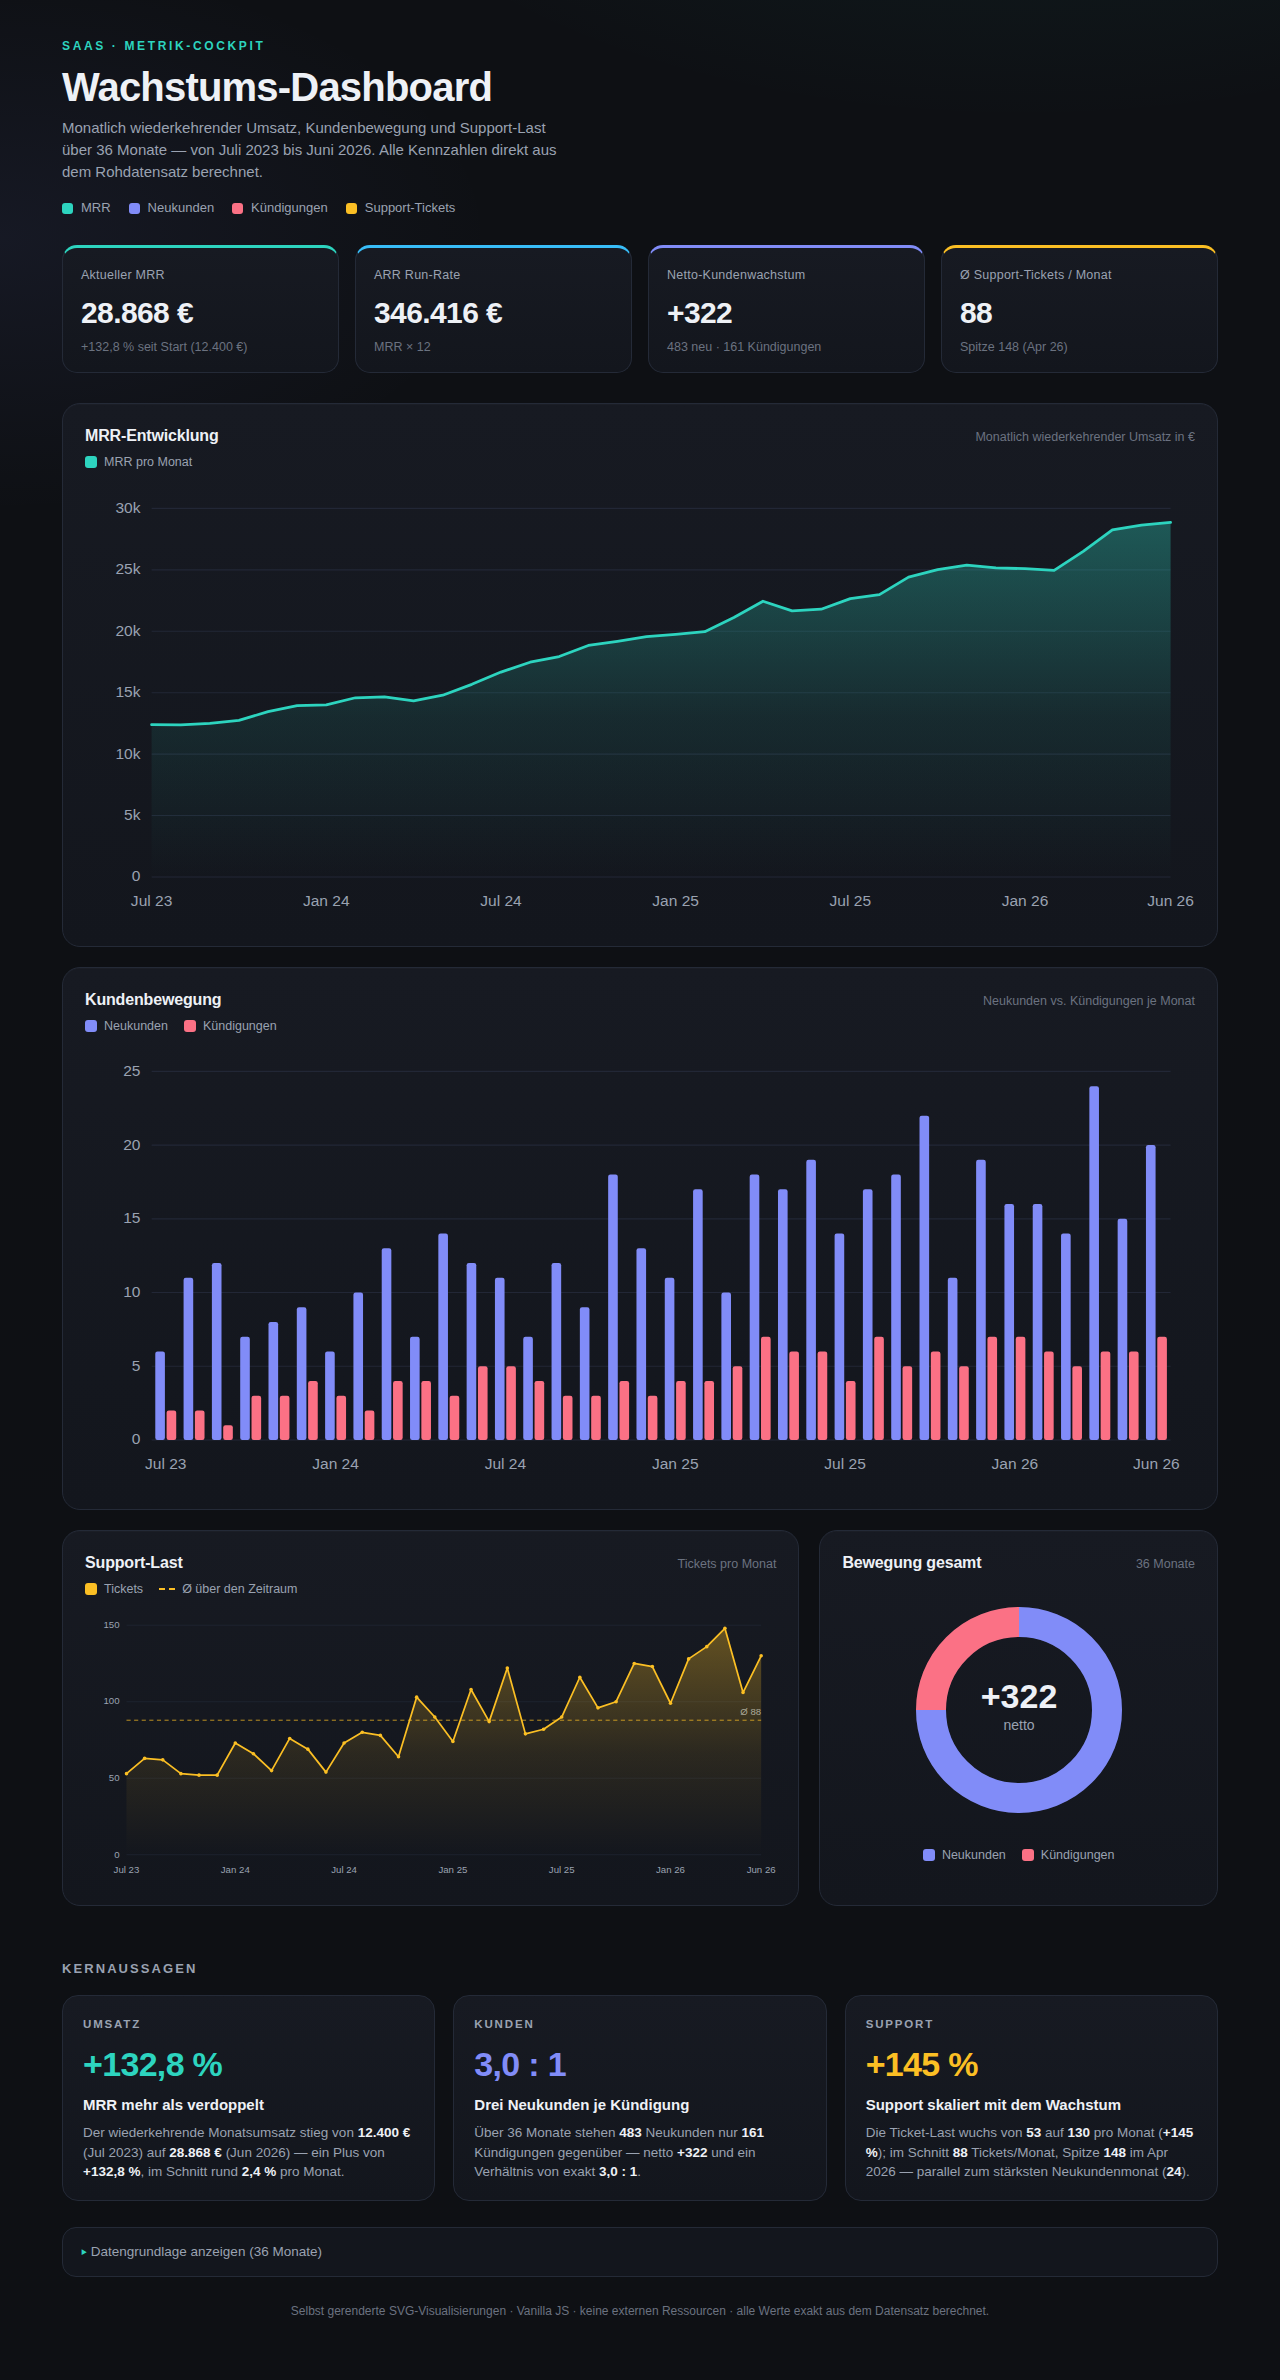 A · Claude Fable 5 · model + harnessB · Claude Haiku 4.5 · model + harness
Screenshots: agi.jetzt renders the stored, model-produced file offline. The file itself is not served. The comparison shows the top of one still frame per run.
Artifact wall · Datenviz-Dashboard mit Insights
5 runs from 5 models on the same brief. A and B put a screenshot into the comparison. Runs from 17 Jul 2026 to 3 Sept 2026.
Check results withdrawn (4 Oct 2026)These check results do not match the screenshots of the same runs. We are therefore withdrawing the results until the check has been repeated in the browser. Affected: three_distinct_visualizations, five_aggregate_matches, three_numeric_insights.
5 of 16 verified v2 runs of this task are published. 5 of the 6 models with recorded runs have a published run.Not published: Phi-4-mini-instruct (1 run; check results withdrawn).Source: the selection records of the published runs. They count the task across its variants and know only models with at least one published run.
- Claude Fable 5Claude Fable 5withdrawn · Check results withdrawn (4 Oct 2026) · 1 format check passed — no check of the result · 2 render and interaction checks not runclaude-code-cli · model + harness18 Jul 2026Open run →
- Claude Haiku 4.5Claude Haiku 4.5withdrawn · Check results withdrawn (4 Oct 2026) · 1 format check passed — no check of the result · 2 render and interaction checks not runclaude-code-cli · model + harness17 Jul 2026Open run →
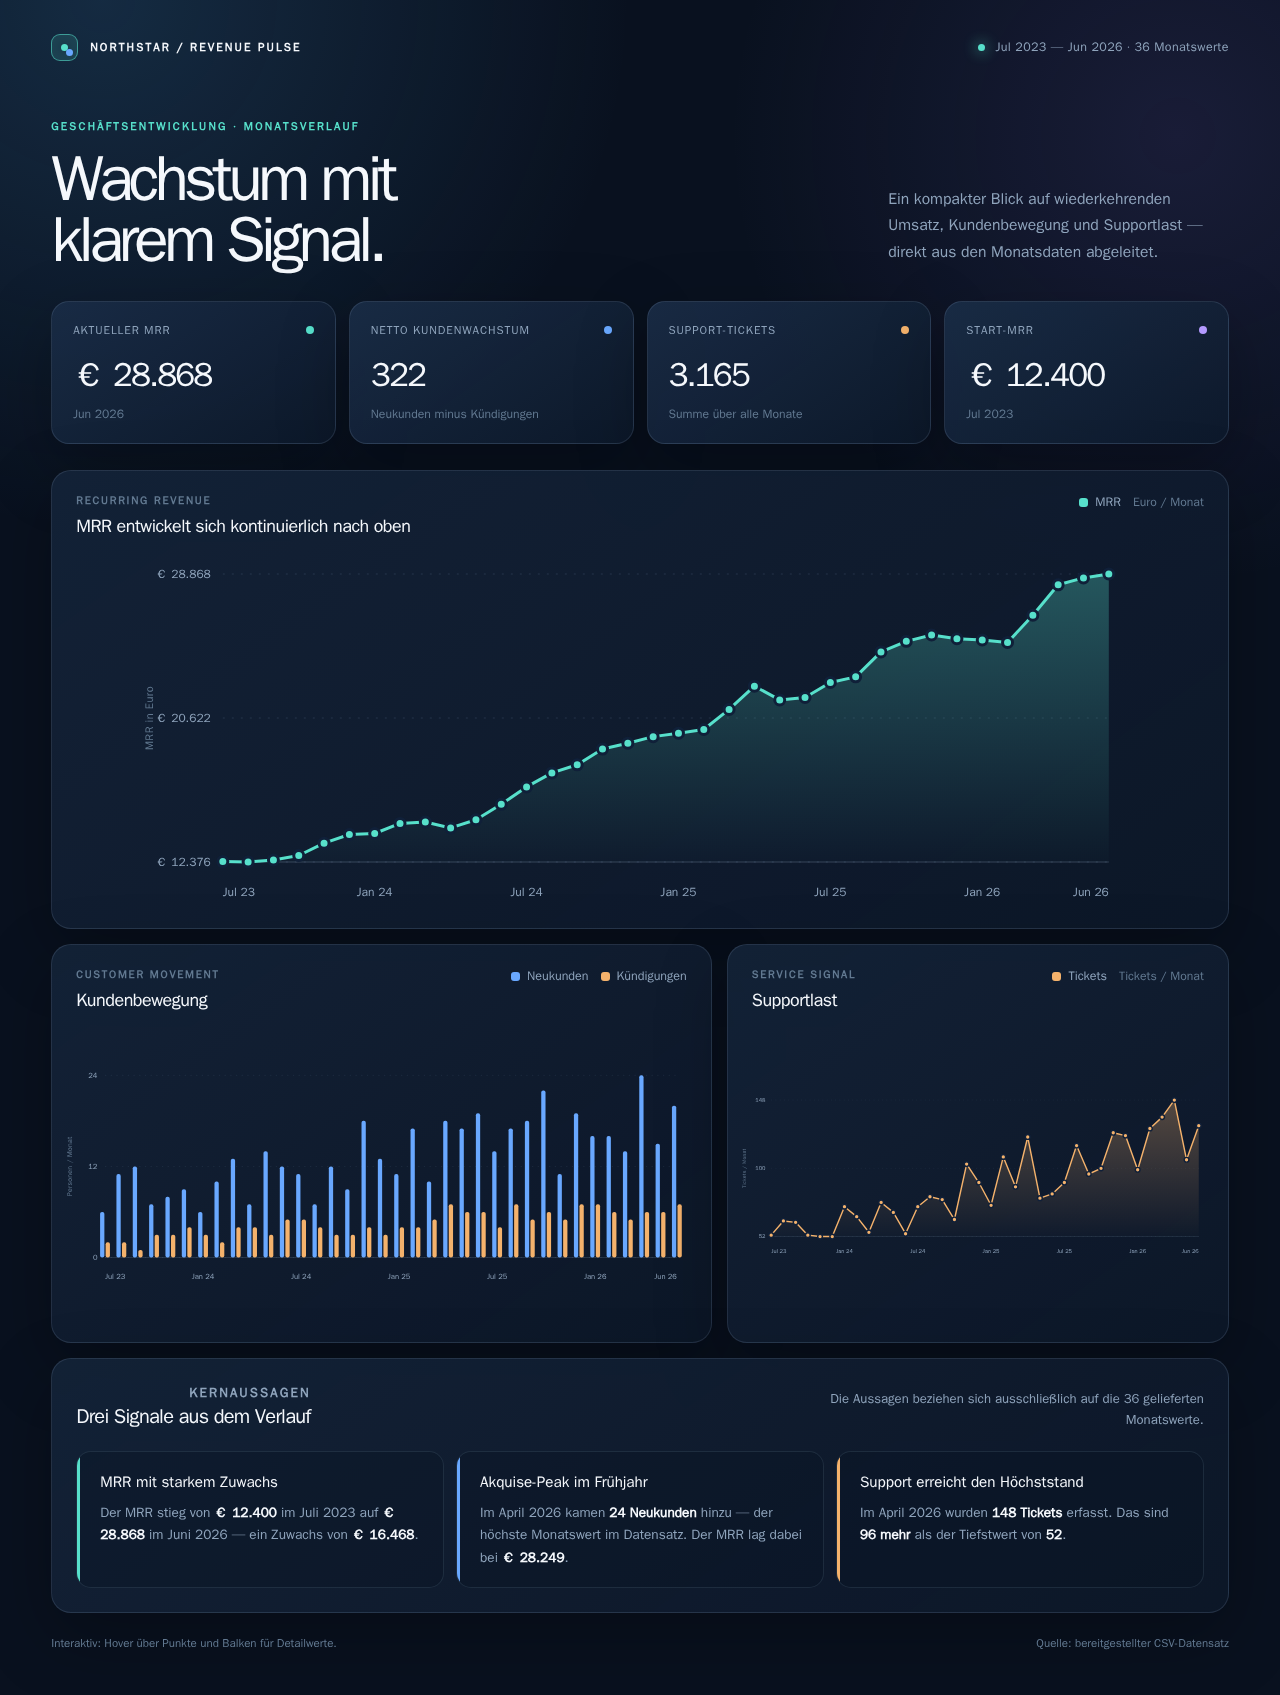 GPT-5.6 LunaGPT-5.6 Lunawithdrawn · Check results withdrawn (4 Oct 2026) · 1 format check passed — no check of the result · 2 render and interaction checks not runcodex-cli · model + harness18 Jul 2026Open run →
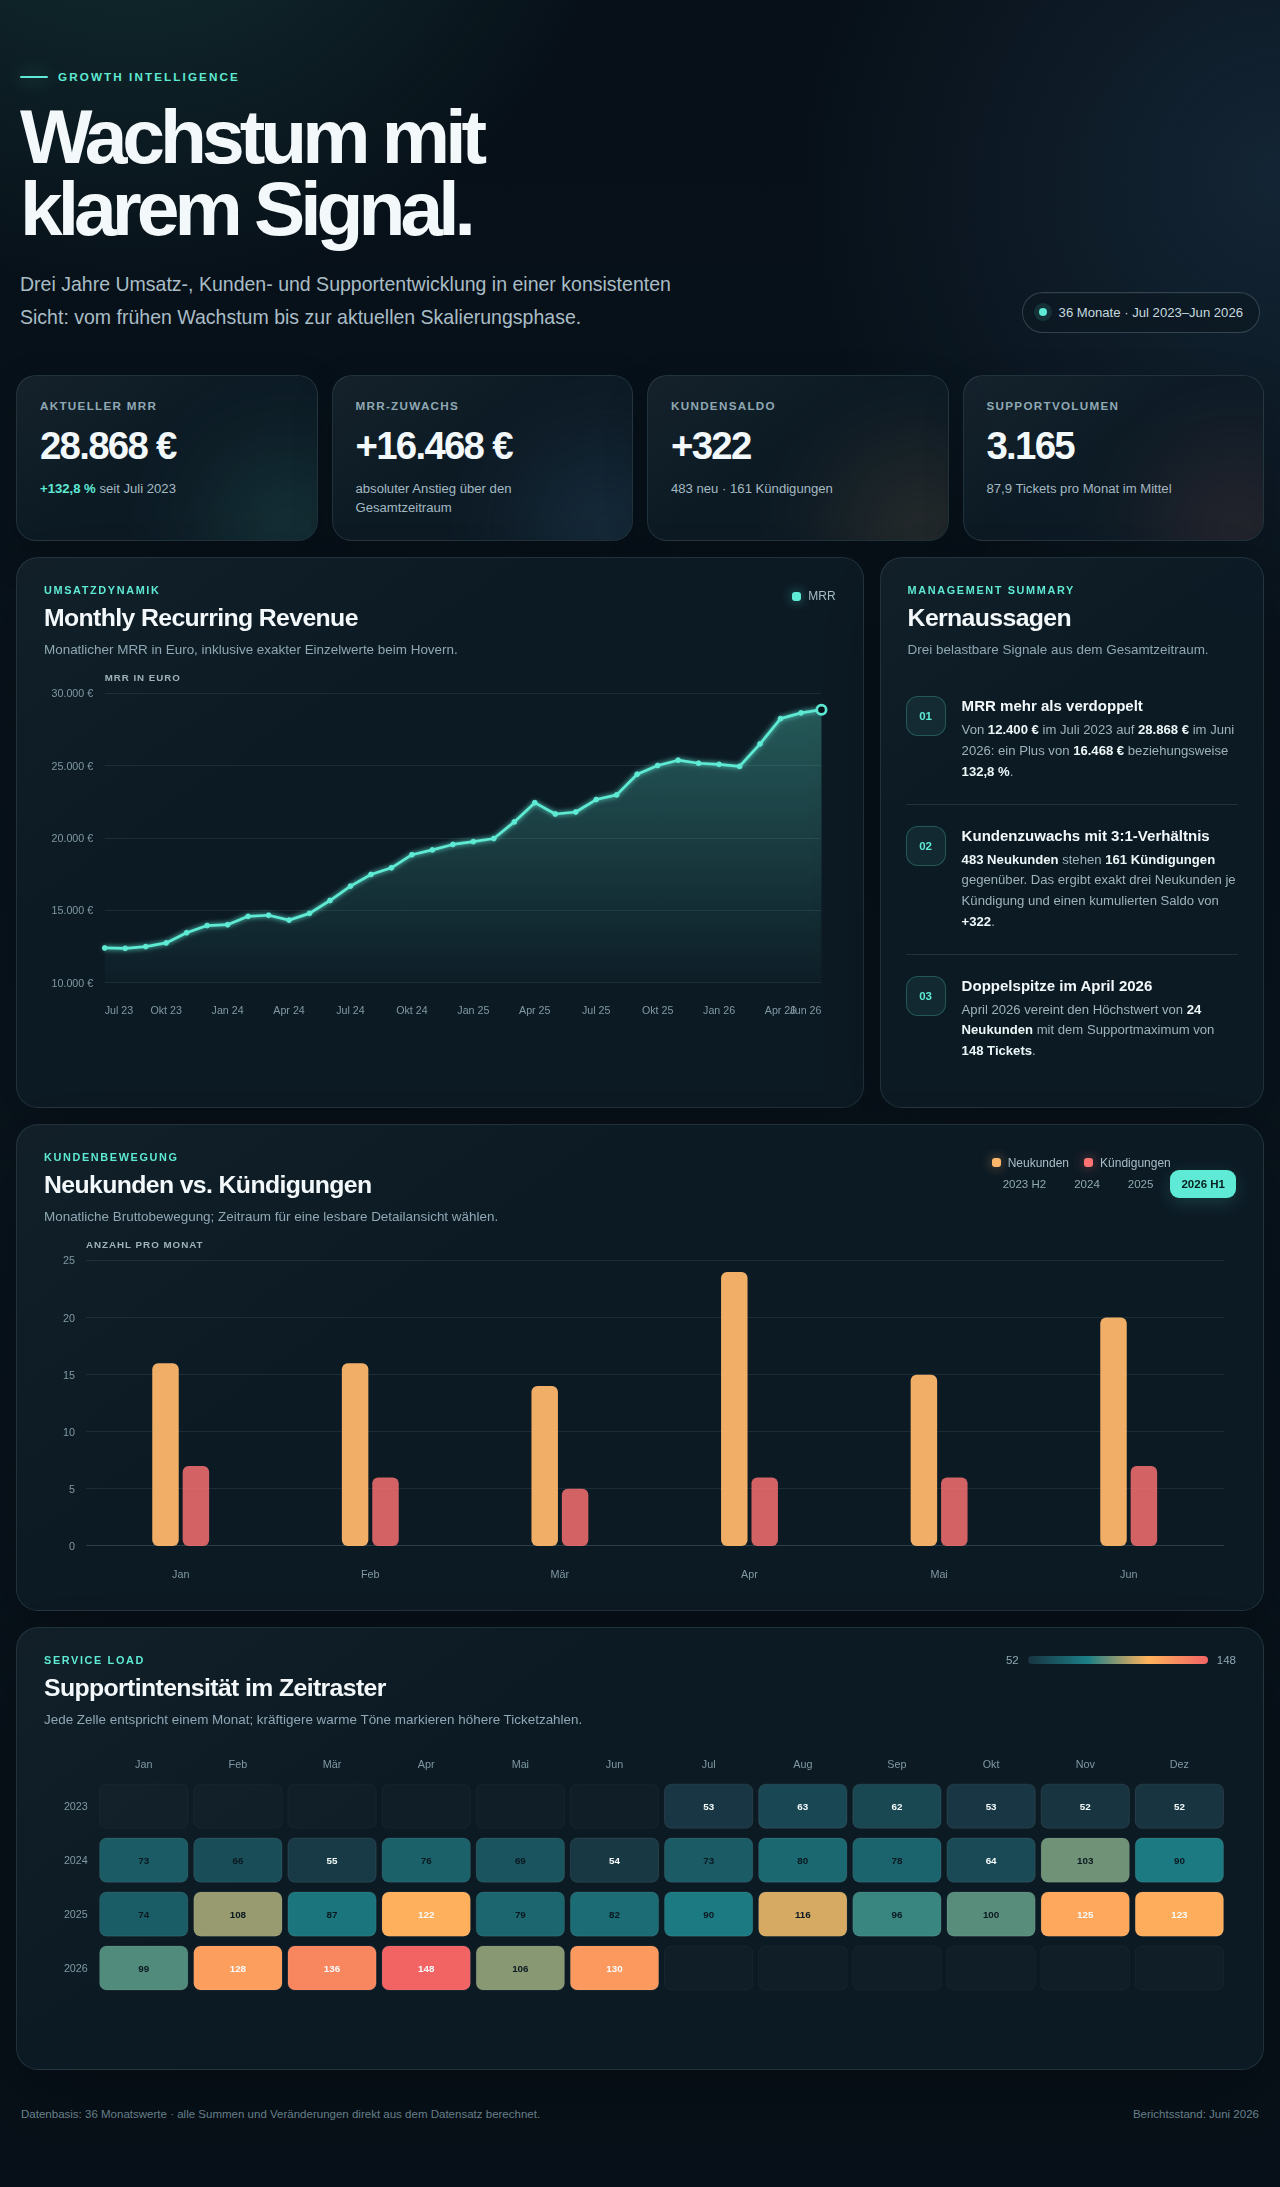 GPT-5.6 SolGPT-5.6 Solwithdrawn · Check results withdrawn (4 Oct 2026) · 1 format check passed — no check of the result · 2 render and interaction checks not runcodex-cli · model + harness17 Jul 2026Open run →
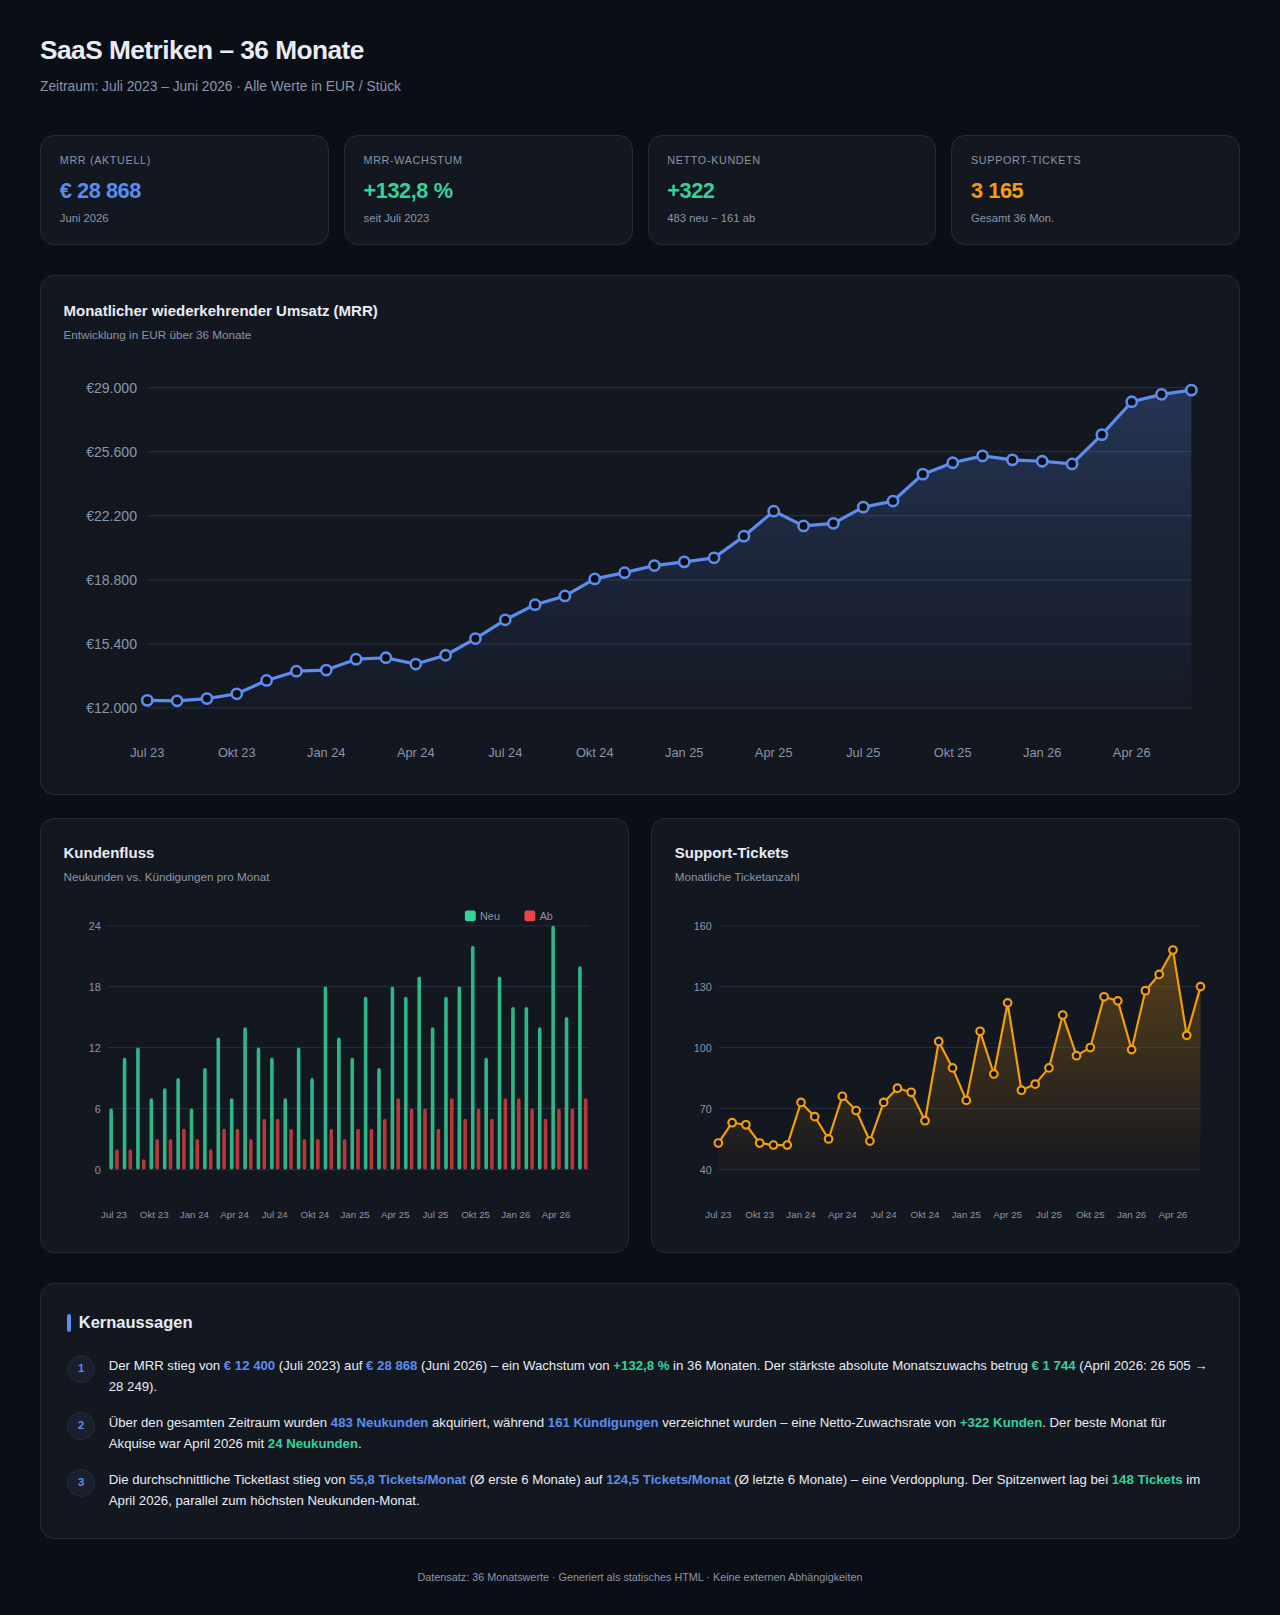 Qwen3.8-27BQwen3.8-27Bwithdrawn · Check results withdrawn (4 Oct 2026) · 1 format check passed — no check of the result · 2 render and interaction checks not runollama · model only3 Sept 2026Open run →
Runs of the same task are not automatically tested alike: runtime, token limit and protocol can differ. Each run lists its own.