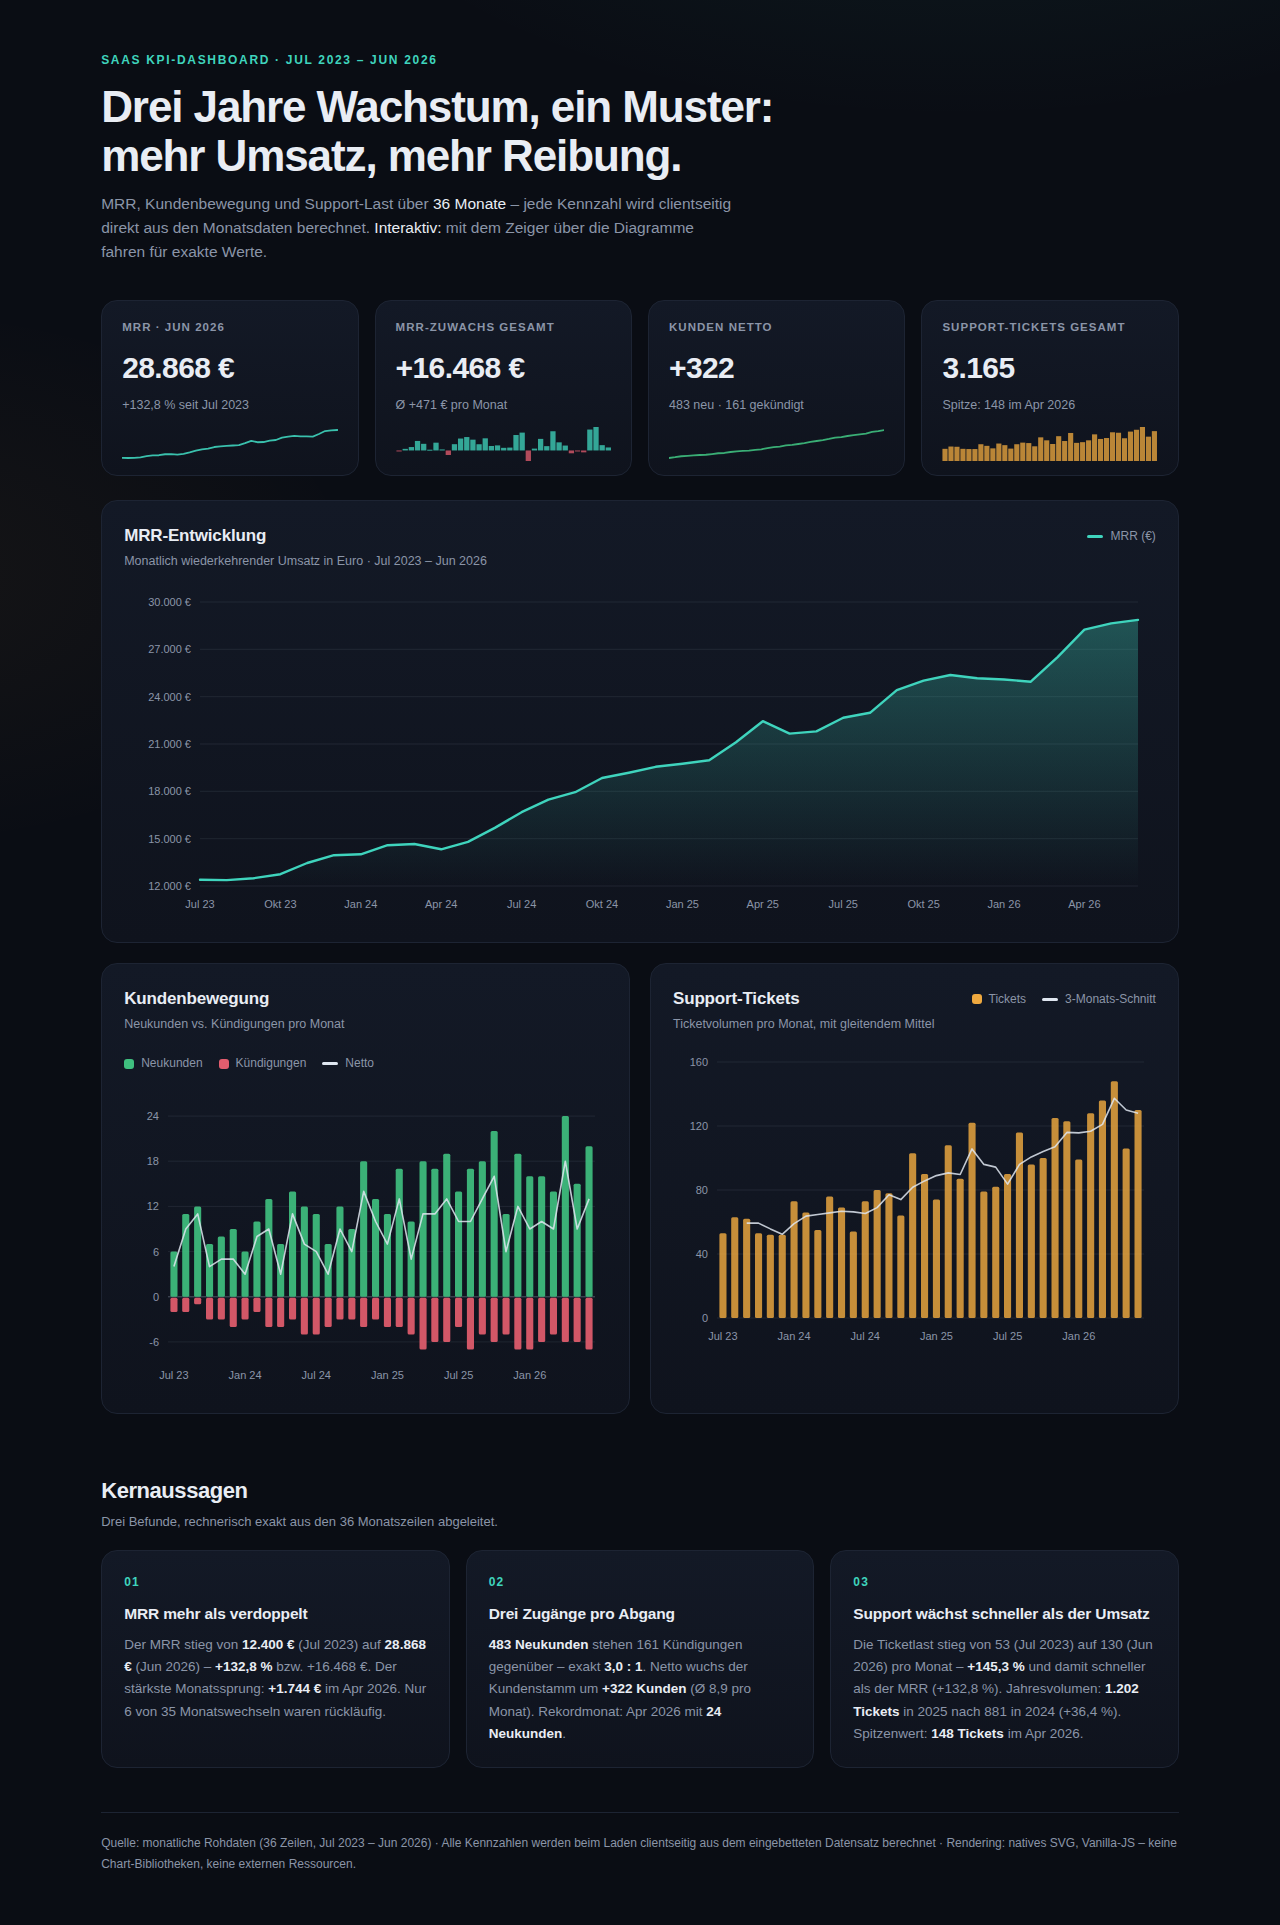
Claude Fable 5
via claude-code-cli 2.1.214model + harness
Run of 18 Jul 2026
Check results withdrawn (4 Oct 2026)
1 format check passed — no check of the result · 2 render and interaction checks not run
Evaluation not published
Archived pilot · Historical run
built by GPT-5.6 Luna via codex-cli 0.144.5 model + harness
Check results withdrawn (4 Oct 2026)These check results do not match the screenshots of the same runs. We are therefore withdrawing the results until the check has been repeated in the browser. Affected: three_distinct_visualizations, five_aggregate_matches, three_numeric_insights.
Rendered by agi.jetzt from the model-produced artifactRendered offline in an isolated renderer from the stored file (sha256 542ecd0073cb…). The file itself is not served.
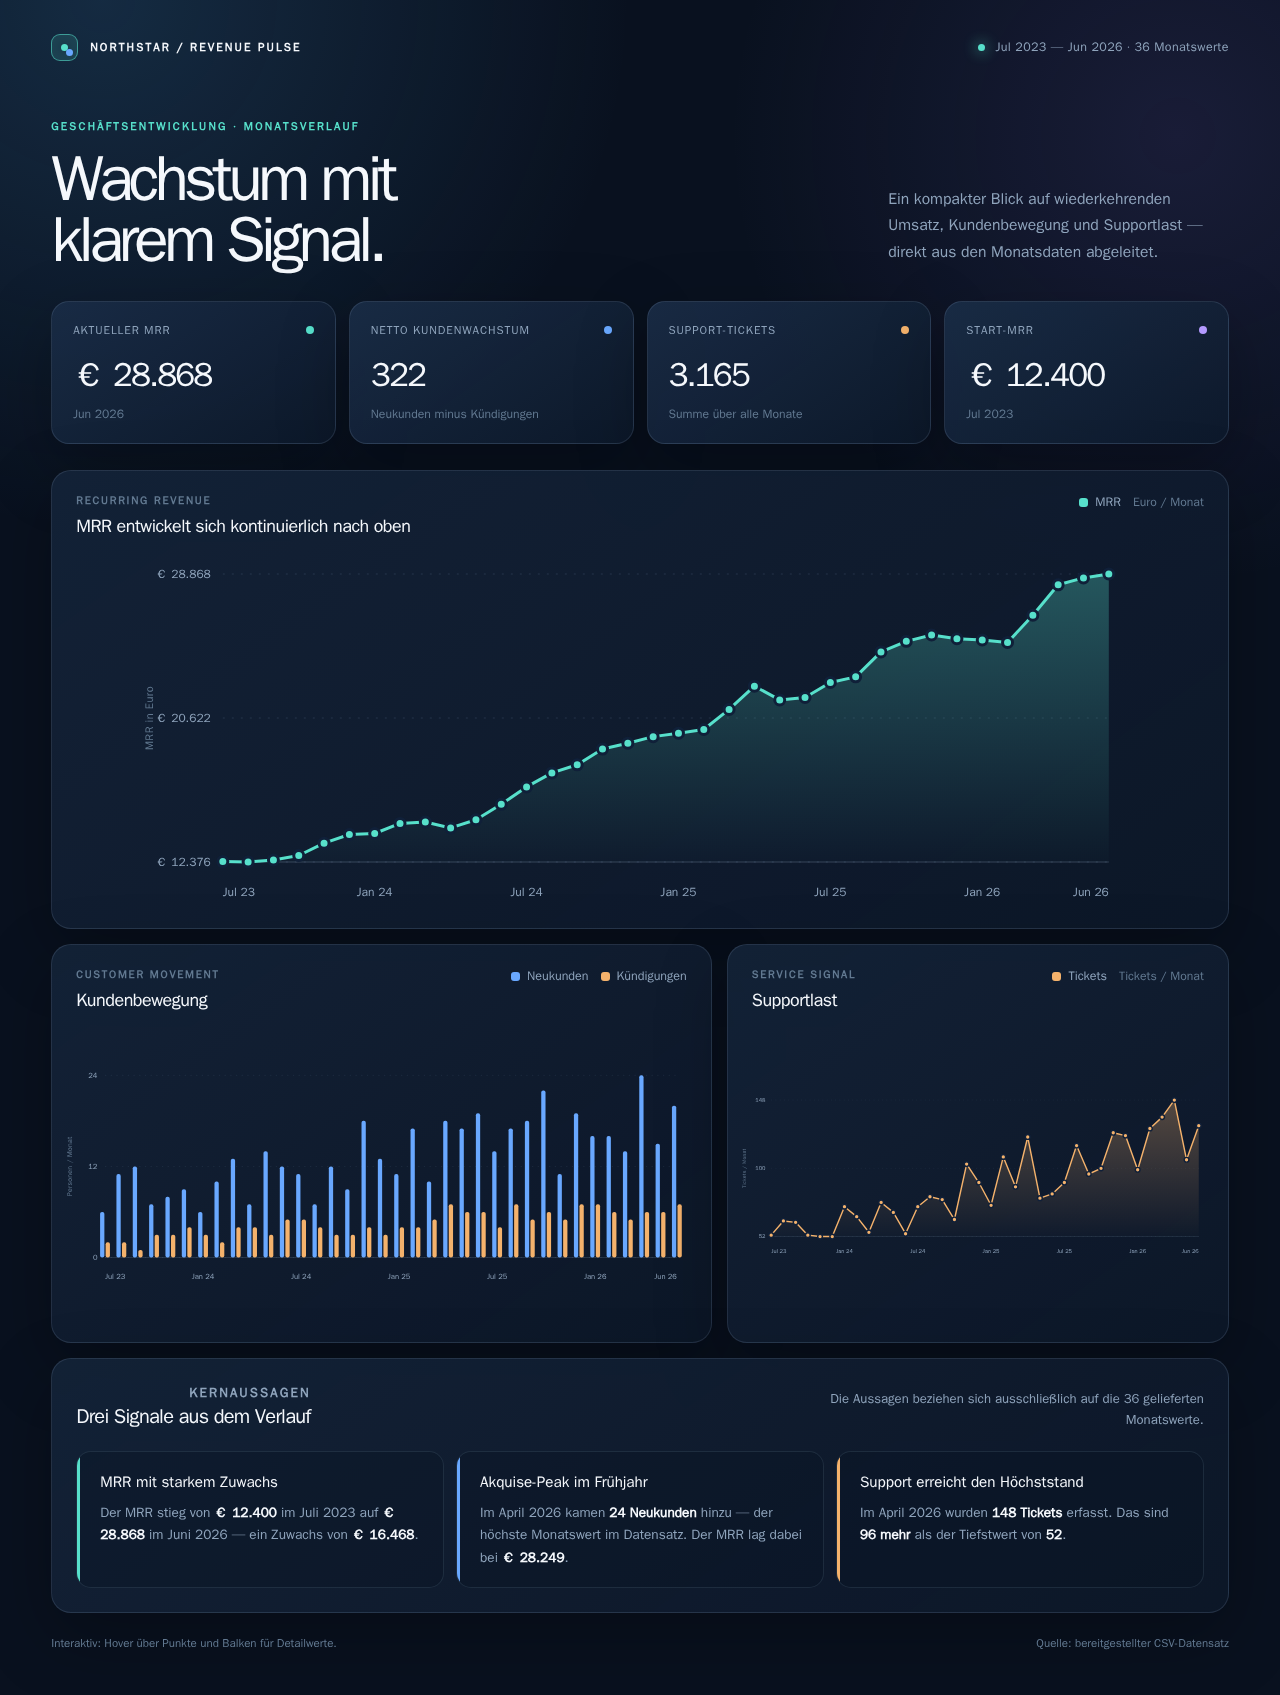
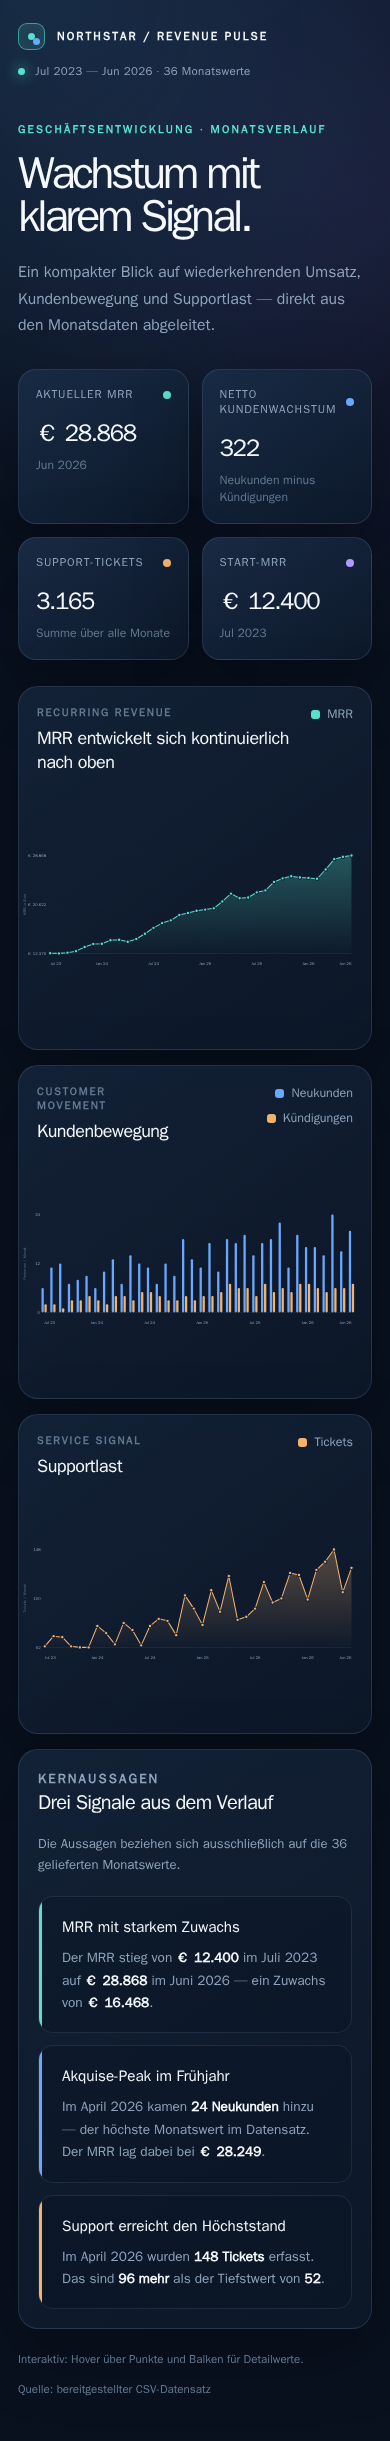
Scroll sideways. Each run had its own runtime and limits — compare the artifacts, not a score.
via claude-code-cli 2.1.214model + harness
Run of 18 Jul 2026
Check results withdrawn (4 Oct 2026)
1 format check passed — no check of the result · 2 render and interaction checks not run
Evaluation not published
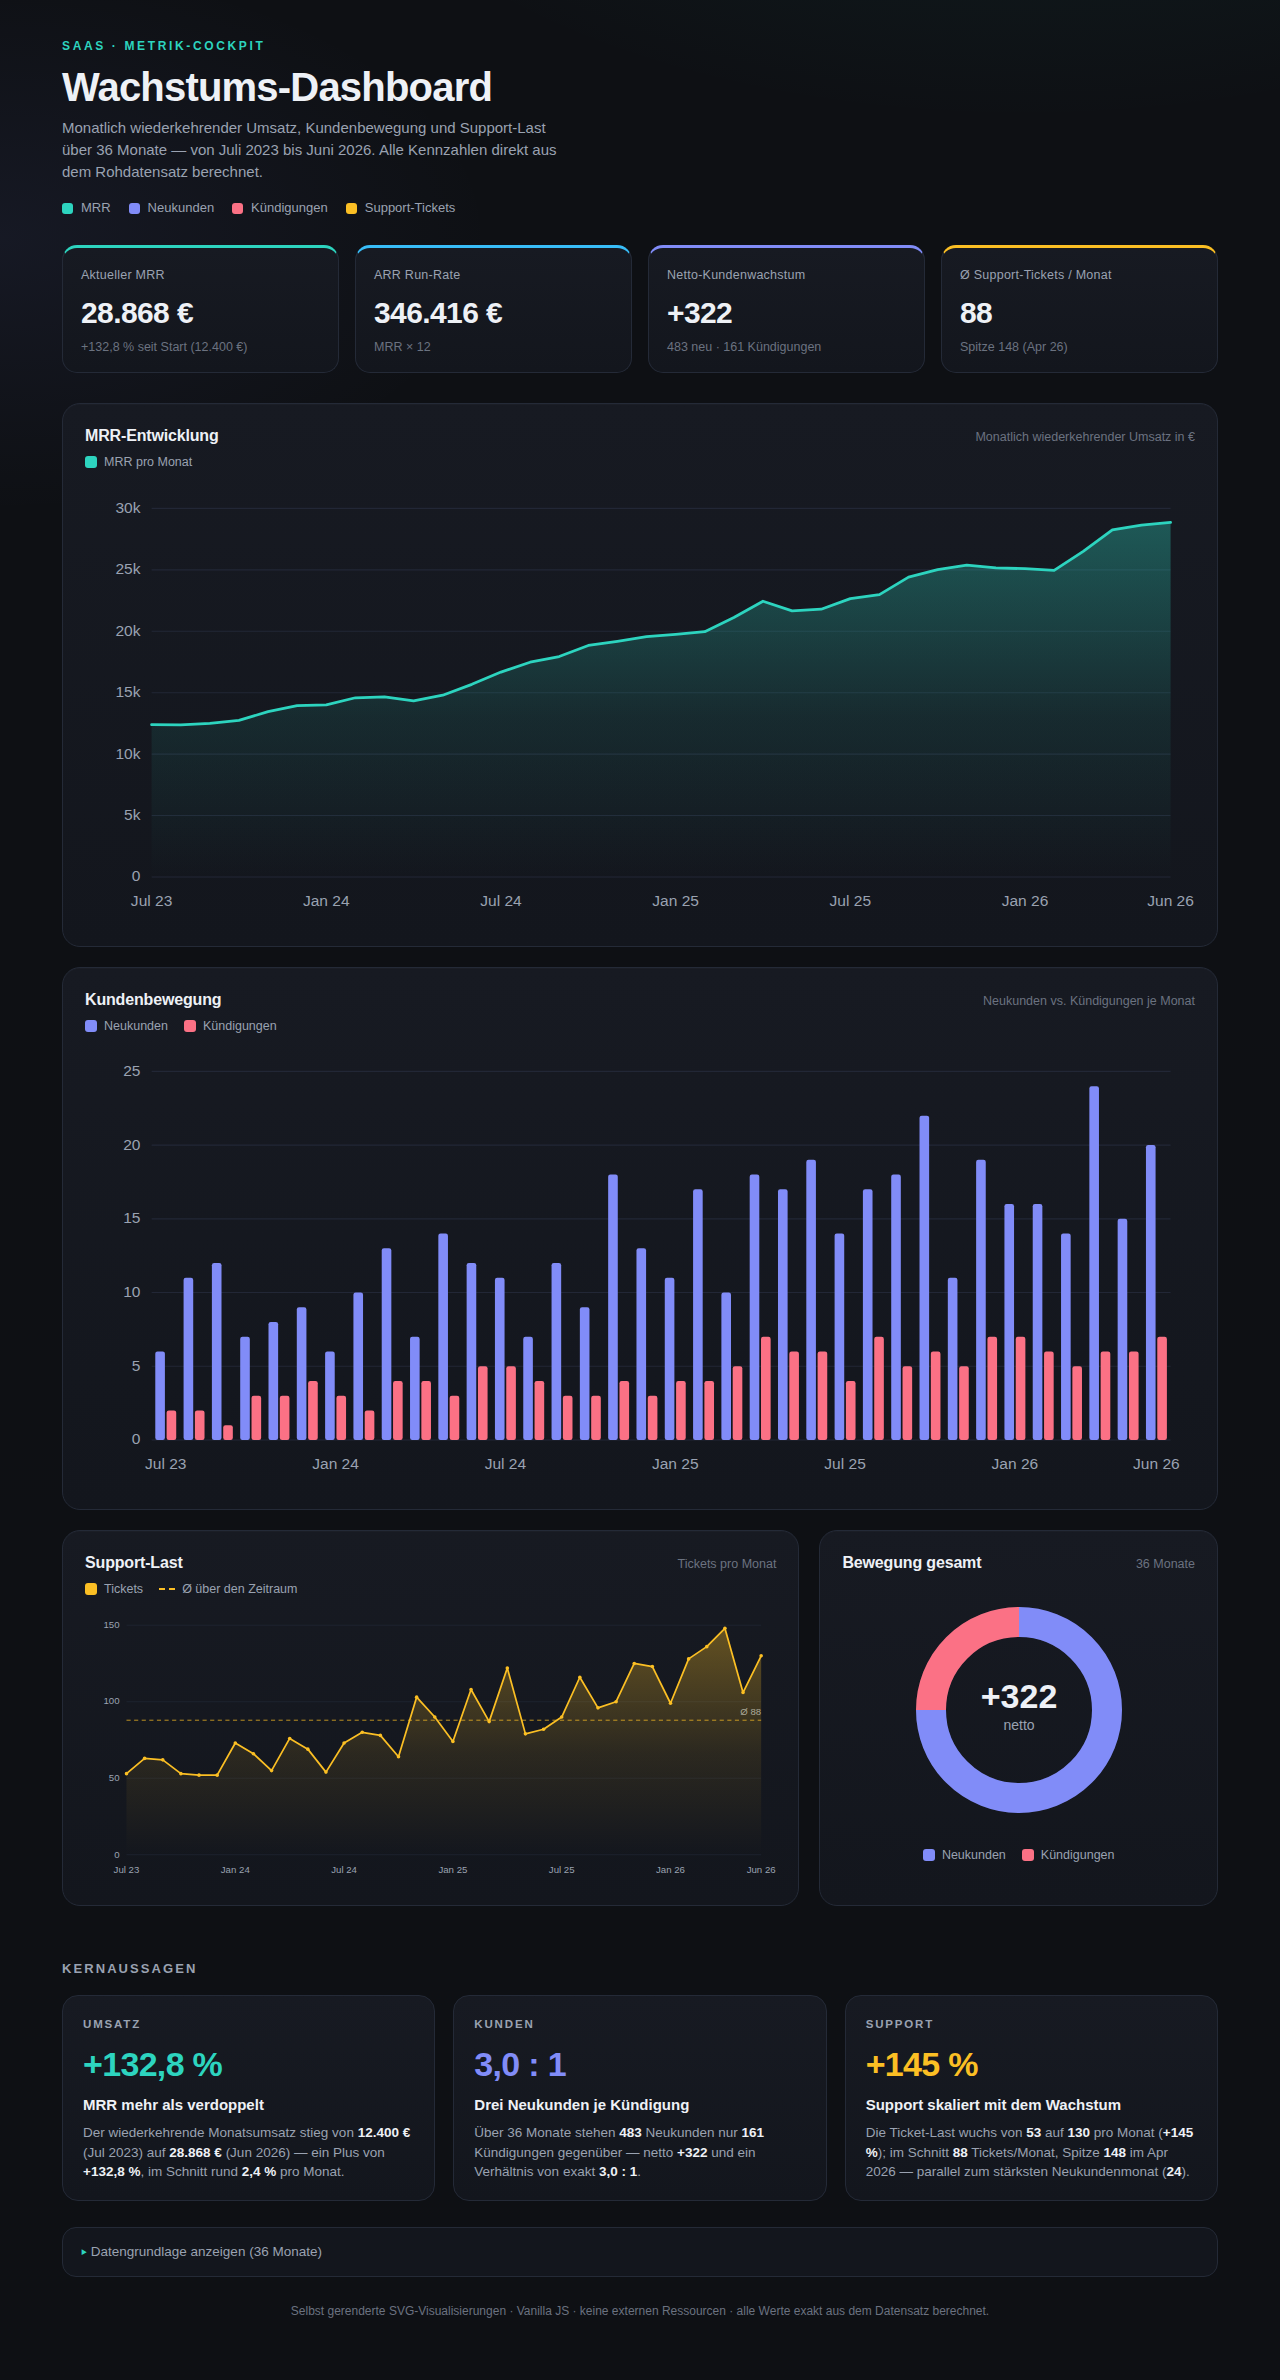
via claude-code-cli 2.1.212model + harness
Run of 17 Jul 2026
Check results withdrawn (4 Oct 2026)
1 format check passed — no check of the result · 2 render and interaction checks not run
Evaluation not published
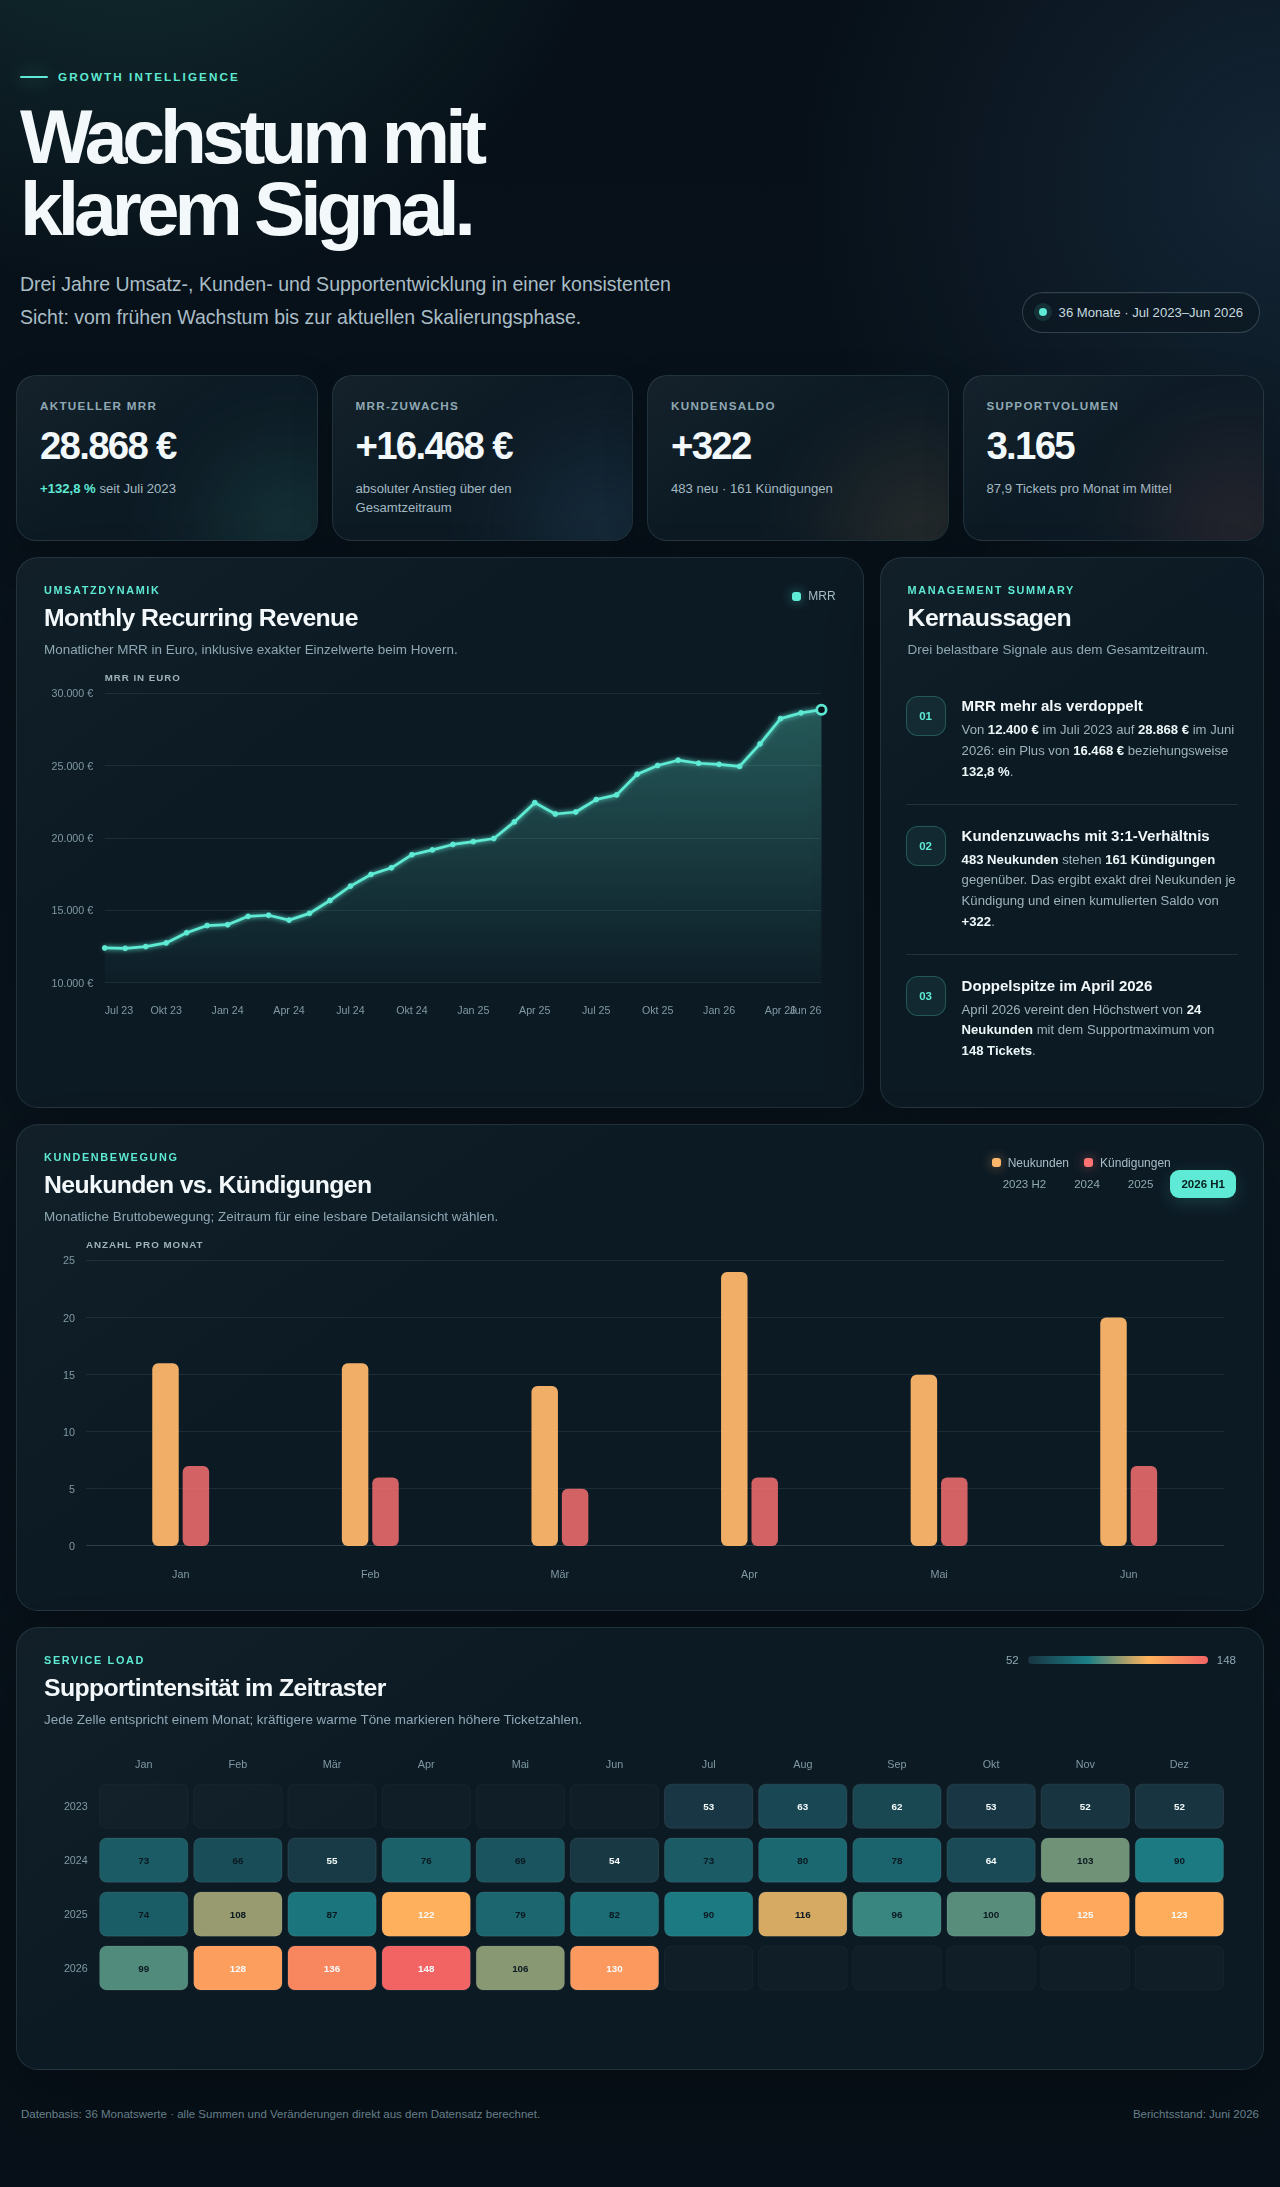
via codex-cli 0.144.5model + harness
Run of 17 Jul 2026
Check results withdrawn (4 Oct 2026)
1 format check passed — no check of the result · 2 render and interaction checks not run
Evaluation not published
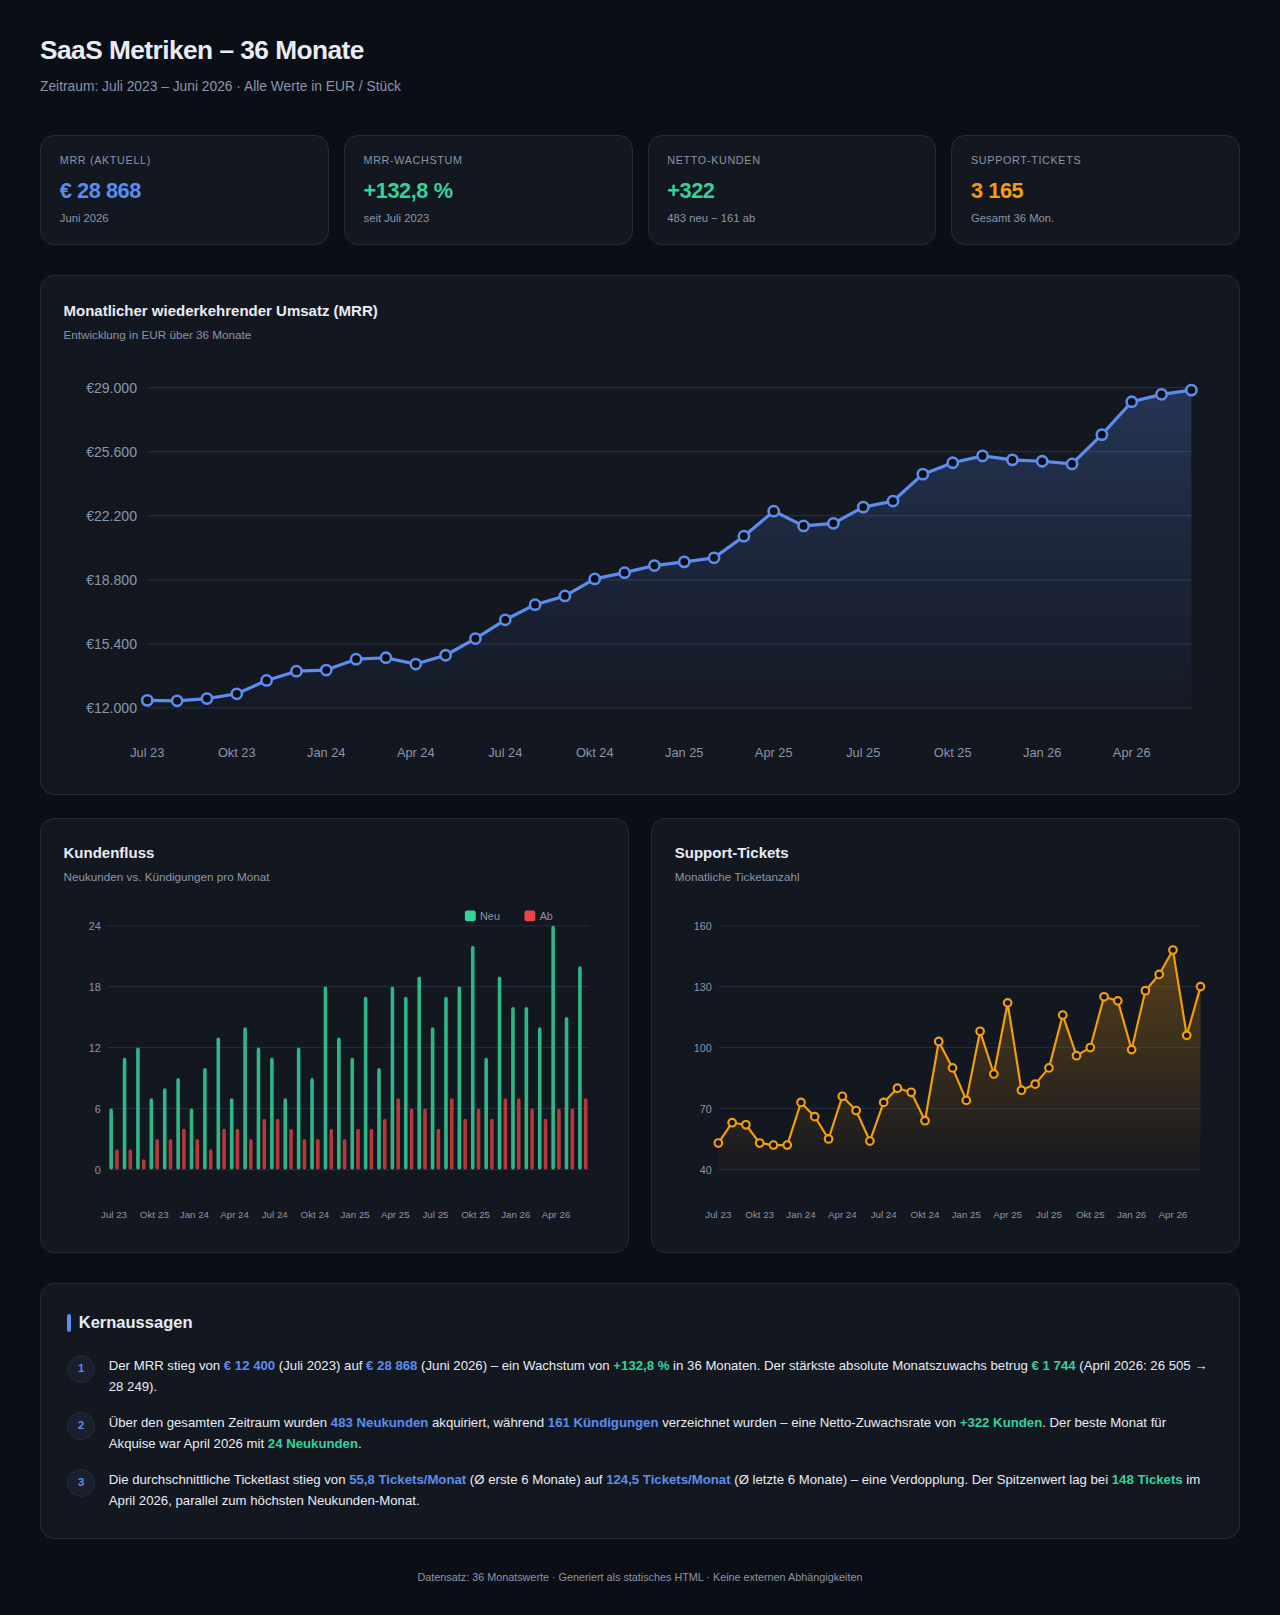
via ollama 0.32.15model only
Run of 3 Sept 2026
Check results withdrawn (4 Oct 2026)
1 format check passed — no check of the result · 2 render and interaction checks not run
Evaluation not published
Automated checks of the stored HTML file, without running it in a browser. Details are the runner’s German originals. Format and presence checks say nothing about whether the result fulfils the brief.
| Check | Kind | Result |
|---|---|---|
| single_html_filegenau eine HTML5-Datei | Format | Passed |
| three_distinct_visualizationsResult withdrawn on 4 Oct 2026; no value is shown. | Content | withdrawn |
| five_aggregate_matchesResult withdrawn on 4 Oct 2026; no value is shown. | Numbers | withdrawn |
| three_numeric_insightsResult withdrawn on 4 Oct 2026; no value is shown. | Content | withdrawn |
| renders_without_errorsSandbox not available — rendering skipped | Rendering | not run |
| no_external_librariesSandbox not available — rendering skipped | Rendering | not run |
2 render and interaction checks were not run. Recorded reason: “Sandbox not available — rendering skipped”.
WhyThe v2 judge record of this run names the tested model as its own judge and lists no criteria. Its score is therefore not shown — nor the combined v2 score, which blends that judge in.
Unten steht ein CSV-Datensatz (ca. 40 Zeilen). Baue daraus eine einzelne HTML-Datei als beeindruckendes, interaktives Dashboard.
Anforderungen:
- Mindestens 3 Visualisierungen, selbst gerendert als SVG oder Canvas — keine Chart-Libraries, keine externen Assets, keine externen Requests.
- Interaktivität mit Vanilla-JS: beim Hovern über Datenpunkte/Balken/Segmente erscheinen präzise Tooltips mit dem konkreten Wert; Achsen und Legenden sind lesbar beschriftet.
- Eine Sektion „Kernaussagen" mit 3 datengestützten Insights; jeder Insight nennt mindestens eine konkrete Zahl aus den Daten.
- Alle gezeigten Zahlen müssen rechnerisch exakt aus dem Datensatz folgen.
- Gestaltung auf Studio-Niveau: klare Hierarchie, stimmige Farbwelt, ruhige Typografie, sinnvoll gewählte Diagrammtypen für die jeweilige Kennzahl. Responsive, kein horizontaler Overflow.
Datensatz:
[CSV, 36 Datenzeilen: Monats-KPIs eines B2B-SaaS (Juli 2023 bis Juni 2026): MRR, Neukunden, Kuendigungen, Support-Tickets.]From the task seed (German original); the actual prompts add output-format instructions and other wording.
Model The runner’s model identifier maps to GPT-5.6 Luna in the agi.jetzt register (verified mapping).
Not an AGI measureThis run shows one thing: what a model built as a single HTML file from a precise brief. It says nothing about general intelligence.Checked automatically in this run: Check results withdrawn (4 Oct 2026) · 1 format check passed — no check of the result · 2 render and interaction checks not run.
5 of 16 verified v2 runs of this task are published. 5 of the 6 models with recorded runs have a published run.Not published: Phi-4-mini-instruct (1 run; check results withdrawn).Source: the selection records of the published runs. They count the task across its variants and know only models with at least one published run.